

In the last week of February 2026 I opened three PRs for security and API contract bugs: a Cypher injection in LightRAG, a misspelled enum value in the OpenAI Python SDK, and hardcoded token decimals in Coinbase AgentKit. This post walks through what I changed in each and what happened next. They all ended differently: one landed through the maintainer's PR, one turned out to be unnecessary, and one is waiting for review.
Three PRs and where they stand#
Statuses and dates come from the PR records on GitHub.
| Project | PR | Topic | Status |
|---|---|---|---|
| HKUDS/LightRAG | #2713 | Cypher injection via workspace label | Closed. My commits were merged through #2792 on March 18, 2026 |
| openai/openai-python | #2893 | prompt_cache_retention value | Closed, already fixed upstream |
| coinbase/agentkit | #965 | Hardcoded 18 decimals in Morpho withdraw | Open |
LightRAG: Cypher injection through the workspace name#
The hole#
LightRAG can store its knowledge graph in Neo4j or Memgraph and separates workspaces with node labels. The API server can read the workspace name from the LIGHTRAG-WORKSPACE HTTP header. In Neo4JStorage and MemgraphStorage, _get_workspace_label() returned that value untouched, and it went into queries through f-strings. The pattern looks like this:
query = f"MATCH (n:`{workspace_label}` {{entity_id: $entity_id}}) RETURN n"Values like $entity_id are passed as parameters, which is correct. The label, though, is pasted into the query text. A header value containing a backtick could close the label and append arbitrary Cypher. lighthousekeeper1212 reported it in #2698, and I picked up the fix.
First commit and the collision problem#
The PostgreSQL backend already sanitized workspace names with re.sub(r"[^a-zA-Z0-9_]", "_", ...), so my first commit applied the same rule to Neo4j and Memgraph and added 20 tests. Then a side effect came up: team-a and team_a map to the same label, so two different workspaces could share data.
In the second commit I stopped stripping characters and escaped backticks by doubling them. Every workspace name now maps to exactly one label:
def _get_workspace_label(self) -> str:
    workspace = self.workspace.strip()
    if not workspace:
        return "base"
    return workspace.replace("`", "``")
Review: escaping depends on context#
The maintainer, danielaskdd, found three problems in review. All three came from using the escaped value everywhere.
- Labels returned by the driver are raw (
foobar), and the code compared them with the escaped value (foo``bar`), so the comparison never matched. - The Memgraph index creation query used the label without backticks, where the escaped value produces invalid Cypher.
- One query used the label as a string literal,
WHERE '{label}' IN labels(n). Doubled backticks mean nothing inside a string, so that query never matched either.
Backtick escaping only applies to an identifier inside backticks. In a string context, bind the raw value as a parameter. Here are both, side by side, with the official neo4j Python driver:
from neo4j import GraphDatabase

def identifier_label(workspace: str) -> str:
    """Label for use inside backticks."""
    return (workspace.strip() or "base").replace("`", "``")

def raw_label(workspace: str) -> str:
    """Label for binding as a query parameter."""
    return workspace.strip() or "base"

def find_entity(driver, workspace: str, entity_id: str):
    label = identifier_label(workspace)
    # Identifier context: escaped value inside backticks
    by_label = f"MATCH (n:`{label}` {{entity_id: $entity_id}}) RETURN n"
    # String context: raw value as a parameter, never interpolated
    by_filter = (
        "MATCH (n) WHERE $label IN labels(n) "
        "AND n.entity_id = $entity_id RETURN n"
    )
    with driver.session() as session:
        first = session.run(by_label, entity_id=entity_id).single()
        second = session.run(
            by_filter, label=raw_label(workspace), entity_id=entity_id
        ).single()
    return first, second

if __name__ == "__main__":
    with GraphDatabase.driver("bolt://localhost:7687", auth=("neo4j", "password")) as driver:
        print(find_entity(driver, "team-a", "Alan Turing"))
How it landed: validation at the entry point too#
danielaskdd took my branch and added a commit on top. The workspace value is now sanitized where it enters the system, both from --workspace / WORKSPACE and from the LIGHTRAG-WORKSPACE header: anything outside [a-zA-Z0-9_] becomes _, with a warning logged when the value changes. The combined change was merged as #2792 on March 18, 2026:
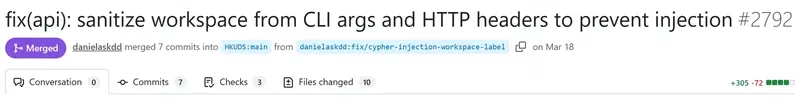
That's why my #2713 shows as closed while my commits are in main. _get_workspace_label() uses my escaping, and a separate helper binds the raw label as a parameter for string contexts. The two layers work together.
Don't rely on a single layer. Validate input against an allowlist at the edge, and escape or parameterize correctly for each context in the query.
OpenAI Python SDK: in-memory or in_memory?#
Issue #2883 pointed out that the SDK typed prompt_cache_retention as Literal["in-memory", "24h"], while the API rejected "in-memory" with a 400 and only accepted "in_memory". The type checker suggested the wrong value and flagged the right one. The bug was in the value's spelling, not the parameter name.
My PR fixed the literal in nine files (+41/−41, across the Chat Completions and Responses types and tests). Six months later a maintainer closed it: the same fix had already landed in main through a commit from the SDK's code generation pipeline. openai-python isn't written by hand. It's generated with Stainless from OpenAI's OpenAPI spec, and the spec is where a lasting fix goes.
Before opening a PR against a generated SDK, read the README and CONTRIBUTING file. For projects like this, a good issue is often more useful than a PR. Correct usage:
from openai import OpenAI

client = OpenAI()

response = client.responses.create(
    model="gpt-5.1",
    input="Summarize this text in three bullet points: ...",
    prompt_cache_retention="24h",  # or "in_memory"
)
print(response.output_text)
Coinbase AgentKit: decimals hardcoded to 18#
AgentKit is a toolkit that lets AI agents act onchain. Its Morpho withdraw action converted the amount with Web3.to_wei(assets, "ether"), and the "ether" unit always means 18 decimals. USDC uses 6. An agent withdrawing 100 USDC would request 100 × 10¹⁸ base units, 10¹² times too many. The bug was reported in #946.
The deposit action in the same provider already did this right by reading decimals() from the token contract. My PR made withdraw follow the same path: it adds a token_address field to the schema, reads decimals through wallet_provider.read_contract(...), converts the amount accordingly, and adds a test for a 6-decimal token.
Here's the conversion on its own, independent of AgentKit and runnable as is:
from decimal import Decimal

def to_atomic(amount: str, decimals: int) -> int:
    value = Decimal(amount)
    if value <= 0:
        raise ValueError("amount must be positive")
    scaled = value.scaleb(decimals)
    if scaled != scaled.to_integral_value():
        raise ValueError(f"{amount} has more than {decimals} decimal places")
    return int(scaled)

assert to_atomic("100", 6) == 100_000_000                 # USDC
assert to_atomic("0.5", 18) == 500_000_000_000_000_000    # WETH
I keep the amount as a Decimal built from a string, never a float, so values like 0.1 don't pick up rounding errors. Reading decimals with web3.py is short:
from web3 import Web3

ERC20_DECIMALS_ABI = [{
    "name": "decimals", "type": "function", "stateMutability": "view",
    "inputs": [], "outputs": [{"name": "", "type": "uint8"}],
}]

w3 = Web3(Web3.HTTPProvider("https://mainnet.base.org"))
usdc = w3.eth.contract(
    address="0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913",  # USDC on Base
    abi=ERC20_DECIMALS_ABI,
)
print(usdc.functions.decimals().call())  # 6
The PR is open and waiting for review:
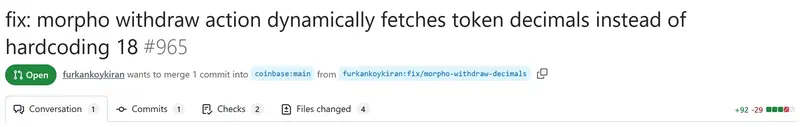
Until it's merged, withdraw in main keeps using to_wei(..., "ether"). If you call it with a token that doesn't use 18 decimals, check the amount yourself.
Three PRs, three endings#
- In LightRAG my code landed, and the fix was complete once the maintainer added validation at the entry point.
- In the OpenAI SDK I fixed a real bug in the wrong place. In a generated codebase, the source spec is where the patch belongs.
- In AgentKit the fix and its test are ready, and the PR is waiting for review.
What's next#
My other contributions from those weeks are in MCP open source contributions and SDK and CLI contributions, and the Go side is in my Keploy contribution. If your own code talks to a graph database, start by checking where the labels and relationship types in your f-string queries come from.


