

Container orchestration with Kubernetes feels easy for the first week: you write a Deployment and the pods come up. The trouble shows up in production. Pods get OOMKilled for no obvious reason, a slow database pushes the whole service into CrashLoopBackOff, and a deploy drops a handful of requests with 502s.
This is a collection of the things tutorials skip and production teaches. I start from one Deployment for a Python API and work through resources, probes, debugging, networking, Secrets and scaling. Everything targets Kubernetes 1.3x.
First: do you need Kubernetes?#
If you run three services on one server, probably not. Docker Compose with Traefik in front, or systemd for services without containers, is far less work. Kubernetes pays for itself when you need to spread across machines, autoscale, roll out without downtime, and give several teams one standard deployment interface. If you're not on a managed cluster (EKS, GKE, AKS and friends), the control plane is yours to maintain too, so count that in.
A production-ready Deployment#
Here's the full manifest; the rest of the post takes it apart:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: api
  labels:
    app: api
spec:
  replicas: 3
  selector:
    matchLabels:
      app: api
  template:
    metadata:
      labels:
        app: api
    spec:
      terminationGracePeriodSeconds: 45
      securityContext:
        runAsNonRoot: true
        seccompProfile:
          type: RuntimeDefault
      topologySpreadConstraints:
        - maxSkew: 1
          topologyKey: kubernetes.io/hostname
          whenUnsatisfiable: ScheduleAnyway
          labelSelector:
            matchLabels:
              app: api
      containers:
        - name: api
          image: ghcr.io/example/api:sha-1a2b3c4
          ports:
            - name: http
              containerPort: 8000
          envFrom:
            - secretRef:
                name: api-secrets
          resources:
            requests:
              cpu: 250m
              memory: 256Mi
            limits:
              memory: 256Mi
          startupProbe:
            httpGet:
              path: /health
              port: http
            periodSeconds: 2
            failureThreshold: 30
          readinessProbe:
            httpGet:
              path: /ready
              port: http
            periodSeconds: 5
          livenessProbe:
            httpGet:
              path: /health
              port: http
            periodSeconds: 10
            failureThreshold: 3
          lifecycle:
            preStop:
              sleep:
                seconds: 10
          securityContext:
            allowPrivilegeEscalation: false
            readOnlyRootFilesystem: true
            capabilities:
              drop: ["ALL"]
          volumeMounts:
            - name: tmp
              mountPath: /tmp
      volumes:
        - name: tmp
          emptyDir: {}
The image comes from the Dockerfile in my post on dockerizing a Python app with uv. It runs as a non-root user, so runAsNonRoot: true passes without changes.
Resources and QoS classes#
requests is what the scheduler reserves when placing the pod. limits is the ceiling the container can't cross. Together they decide the pod's QoS class:
- Guaranteed: every container has CPU and memory requests equal to its limits. Under memory pressure, these are evicted last.
- Burstable: at least one request is set, but the Guaranteed conditions aren't met. Most web services live here.
- BestEffort: no requests or limits at all. First to go when a node runs short. I don't run these in production.
Memory and CPU limits behave differently. Exceed the memory limit and the kernel kills the container, which is your OOMKilled. Exceed the CPU limit and the container is throttled, not killed. So my default is a memory limit equal to the request, a CPU request, and no CPU limit. The memory limit keeps a leak from hurting other pods on the node; skipping the CPU limit stops the service from being slowed down artificially while CPU sits idle. It's a debated choice, and on multi-tenant clusters or with cost allocation you may need CPU limits anyway.
Set requests from measurements, not guesses; a few days of kubectl top pods shows real usage. With in-place pod resize, GA in Kubernetes 1.35, you can also change a running pod's resources without restarting it.
Probes: startup, readiness, liveness#
Mixing these up causes cascading failures:
- The startupProbe runs while the app boots. The other two don't start until it passes, which keeps liveness from killing a slow starter before it's up.
- The readinessProbe asks "can you take traffic?". On failure the pod is removed from the Service endpoints but not restarted.
- The livenessProbe asks "are you stuck?". On failure the container is restarted.
The mistake I see most is a liveness probe that checks the database. When the database slows down, every pod fails liveness, every pod restarts, each one opens fresh connections on startup, and the database gets worse. My rule: /health only checks that the process answers, never external dependencies. The database check lives in /ready. With the database gone, pods stop receiving traffic but aren't restarted.
How the 10-second preStop sleep and terminationGracePeriodSeconds fit together, along with signal handling in the app, is in my post on graceful shutdown.
What I do on CrashLoopBackOff#
When pods keep restarting, I go through these in order:
kubectl get pods -l app=api                 # the RESTARTS column
kubectl logs deploy/api --previous          # last logs of the container that died
kubectl describe pod <pod-name>             # Last State, Reason, Events
kubectl get events --sort-by=.lastTimestamp # cluster-level events
--previous is the flag that matters. Plain kubectl logs shows the freshly restarted container, which usually has nothing but a startup message. The stack trace is in the previous, dead container. The Reason field in describe shows infrastructure causes like OOMKilled, Error or ContainerCannotRun. ImagePullBackOff usually means a wrong tag or missing registry credentials.
For distroless images with no shell, attach an ephemeral debug container:
kubectl debug -it <pod-name> --image=busybox:1.37 --target=apiServices and exposure: Gateway API instead of Ingress#
Service types are simple:
- ClusterIP is reachable only inside the cluster. The default for service-to-service traffic.
- NodePort opens a port on every node. I rarely use it directly in production.
- LoadBalancer asks the cloud provider for a load balancer.
For years, HTTP exposure meant an Ingress resource and the ingress-nginx controller. The Kubernetes project has retired ingress-nginx: maintenance has ended and the repository is archived. Existing installs keep working, but there are no more security fixes.
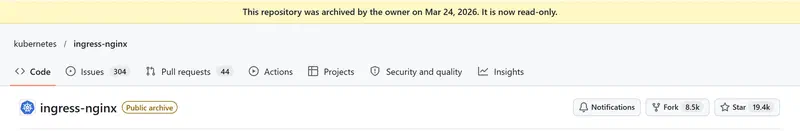
On new clusters I use the Gateway API, which has many implementations, including Envoy Gateway, Cilium, Istio, NGINX Gateway Fabric and Traefik.
apiVersion: v1
kind: Service
metadata:
  name: api
spec:
  selector:
    app: api
  ports:
    - port: 80
      targetPort: http
---
apiVersion: gateway.networking.k8s.io/v1
kind: HTTPRoute
metadata:
  name: api
spec:
  parentRefs:
    - name: public-gateway
      namespace: gateway-system
  hostnames:
    - api.example.com
  rules:
    - matches:
        - path:
            type: PathPrefix
            value: /
      backendRefs:
        - name: api
          port: 80
With those two resources, a request's path looks like this: the Gateway accepts it, the HTTPRoute hands it to the api Service, and the Service spreads it across ready pods on different nodes.
What I like most about the Gateway API is the split in roles. The cluster admin owns the Gateway (listeners, TLS certificates) and app teams write only their own HTTPRoute. Things that needed controller-specific annotations on Ingress, like weighted routing or header matching, are standard fields here.
ConfigMaps and Secrets#
Secrets are base64-encoded by default, not encrypted. Anyone allowed to run kubectl get secret -o yaml can read them. What to do about it:
- Check that encryption at rest for etcd is on. Managed clusters usually enable it; on a self-built cluster it's your job.
- Narrow who can read Secrets with RBAC.
- Keep plaintext Secrets out of Git. The two common options: Sealed Secrets, which stores an encrypted object in Git that only the cluster can decrypt, or the External Secrets Operator, which pulls values from a vault such as AWS Secrets Manager or HashiCorp Vault. If a vault already exists, I go with the second.
Scaling: HPA and PodDisruptionBudget#
The Horizontal Pod Autoscaler changes the replica count based on metrics. It needs metrics-server in the cluster; if kubectl top pods errors out, HPA won't work either.
apiVersion: autoscaling/v2
kind: HorizontalPodAutoscaler
metadata:
  name: api
spec:
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: api
  minReplicas: 3
  maxReplicas: 10
  metrics:
    - type: Resource
      resource:
        name: cpu
        target:
          type: Utilization
          averageUtilization: 70
---
apiVersion: policy/v1
kind: PodDisruptionBudget
metadata:
  name: api
spec:
  minAvailable: 2
  selector:
    matchLabels:
      app: api
averageUtilization: 70 means 70 percent of the CPU request, so a badly sized request makes HPA decide badly too. With HPA in place, make sure your GitOps tool isn't writing the Deployment's replicas back on every sync, or the two will fight.
A PodDisruptionBudget caps how many pods can go down at once during voluntary disruptions like node maintenance. kubectl drain <node> --ignore-daemonsets respects it while evicting pods, and kubectl uncordon <node> lets the node take pods again afterwards.
Stateful workloads and storage#
Pods in a Deployment are interchangeable, get random names, and can be deleted and recreated at any time. In a StatefulSet, pods keep stable names (db-0, db-1) and each gets its own persistent volume; they start and stop in order. Databases, Kafka and Redis run as StatefulSets.
With storage, watch the access mode. Cloud block disks (EBS, Persistent Disk) are usually ReadWriteOnce: one node can attach them at a time. If several pods on different nodes must write to the same volume, you need storage that supports ReadWriteMany, such as NFS or EFS. Before moving a production database into Kubernetes, I'd look hard at a managed database service. Operating stateful systems in a cluster takes far more effort than operating a stateless API.
Network policies and RBAC#
By default every pod can talk to every other pod. An attacker who owns a web pod can connect straight to the database. I start with a namespace-wide deny and then open what's needed:
apiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
  name: default-deny-ingress
spec:
  podSelector: {}
  policyTypes:
    - Ingress
---
apiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
  name: db-from-api
spec:
  podSelector:
    matchLabels:
      app: database
  policyTypes:
    - Ingress
  ingress:
    - from:
        - podSelector:
            matchLabels:
              app: api
      ports:
        - port: 5432
The CNI plugin is what enforces NetworkPolicy. Cilium and Calico do; some simple CNIs accept the objects and enforce nothing. After writing a policy, test that it actually blocks traffic.
For RBAC my rule is simple: nobody gets cluster-admin. Developers get a Role and RoleBinding in their own namespace; CI gets only what it needs in the namespaces it deploys to.
Helm, GitOps and service meshes#
Helm is good for installing packaged software. For my own services I avoid charts with hundreds of lines where every field is wrapped in an if; Kustomize over plain manifests is usually easier to read. Changes reach the cluster from Git through a GitOps tool such as Argo CD or Flux, not through kubectl apply in CI, so the answer to "what is running?" is always in Git. The CI half is in my GitHub Actions CI/CD post.
A service mesh (Istio, Linkerd) brings mTLS, fine-grained traffic control and service-to-service observability, and it also brings complexity and resource cost. Without dozens of services and a concrete need for those features, I wouldn't install one.
Pre-production checklist#
- Does every container have a memory request and limit?
- Are startup, readiness and liveness probes separate, with liveness ignoring external dependencies?
- Is there a
preStoppause and a long enoughterminationGracePeriodSeconds? - Do pods run as non-root with
allowPrivilegeEscalation: false? - Are pods spread across nodes with
topologySpreadConstraints? - Are a PDB and an HPA in place?
- Is there a default-deny NetworkPolicy, and does your CNI enforce it?
- Are Secrets kept out of Git in plaintext?
What's next#
To try these manifests locally, kind or k3d gives you a cluster in a few minutes. As a first experiment, delete a pod with kubectl delete pod and watch readiness and the preStop pause keep requests flowing. For building and tagging the image in CI, see my GitHub Actions CI/CD post; for the shutdown side, the graceful shutdown post. Every field is documented in the Kubernetes docs, and the Gateway API has its own site.


